Unit 3.
Case Study: Scaling Food Delivery During Festivals – Infra Under Surge
Learning Objectives
By the end of this case study, you will be able to analyze and apply architectural patterns for high-traffic e-commerce events.
- ✅ Analyze the impact of bursty, seasonal traffic on a typical e-commerce platform.
- ✅ Identify key architectural solutions like caching, queues, and database scaling.
- ✅ Evaluate the success of infrastructure changes using performance metrics (latency, error rates).
- ✅ Apply these scaling concepts to the local Nepali e-commerce context.
The Challenge: The Festival Surge
Platforms like Foodmandu or Pathao Food face massive, predictable traffic spikes during festivals like Dashain and Tihar.
The Domino Effect of Unpreparedness:
Massive Traffic Spike 📈
➜ App/API Slowdowns 🐌
➜ Database Overload & Timeouts 💥
➜ Failed Orders & Payments ❌
➜ Unhappy Customers & Overwhelmed Support 😠
Interactive: Traffic Surge Simulator
Drag the slider to simulate festival traffic. Observe how load affects your infrastructure in real time.
🌍 Real Case: Two DoorDash Surge Problems
- Campaign traffic: an AWS case study describes DoorDash's football-championship sweepstakes using CloudFront, API Gateway, SQS and Lambda.
- The team stress-tested and pre-scaled frequently used components. Queues decoupled entry submission from later processing.
- Delivery operations: DoorDash engineers separately describe peak dispatch pressure, including Super Bowl demand, and a redesign separating coordination from distributed computation.
- A fast promotional website is not the same as a reliable food-delivery operation: kitchens, couriers and routing still have limits.
Transfer the preparation and decoupling principles to a Dashain/Tihar scenario, not the companies' traffic numbers or private implementation details.
🎬 Watch: Orders as Events
A Multi-Layered Solution
The solution wasn't a single fix, but a combination of strategies targeting different parts of the system.
1. Aggressive Caching
Serve content faster by reducing direct hits to the main server and database.
2. Database Optimization
Strengthen the core data layer to handle both high read and write volumes efficiently.
3. Asynchronous Workflows
Decouple system components to handle order processing resiliently, even under load.
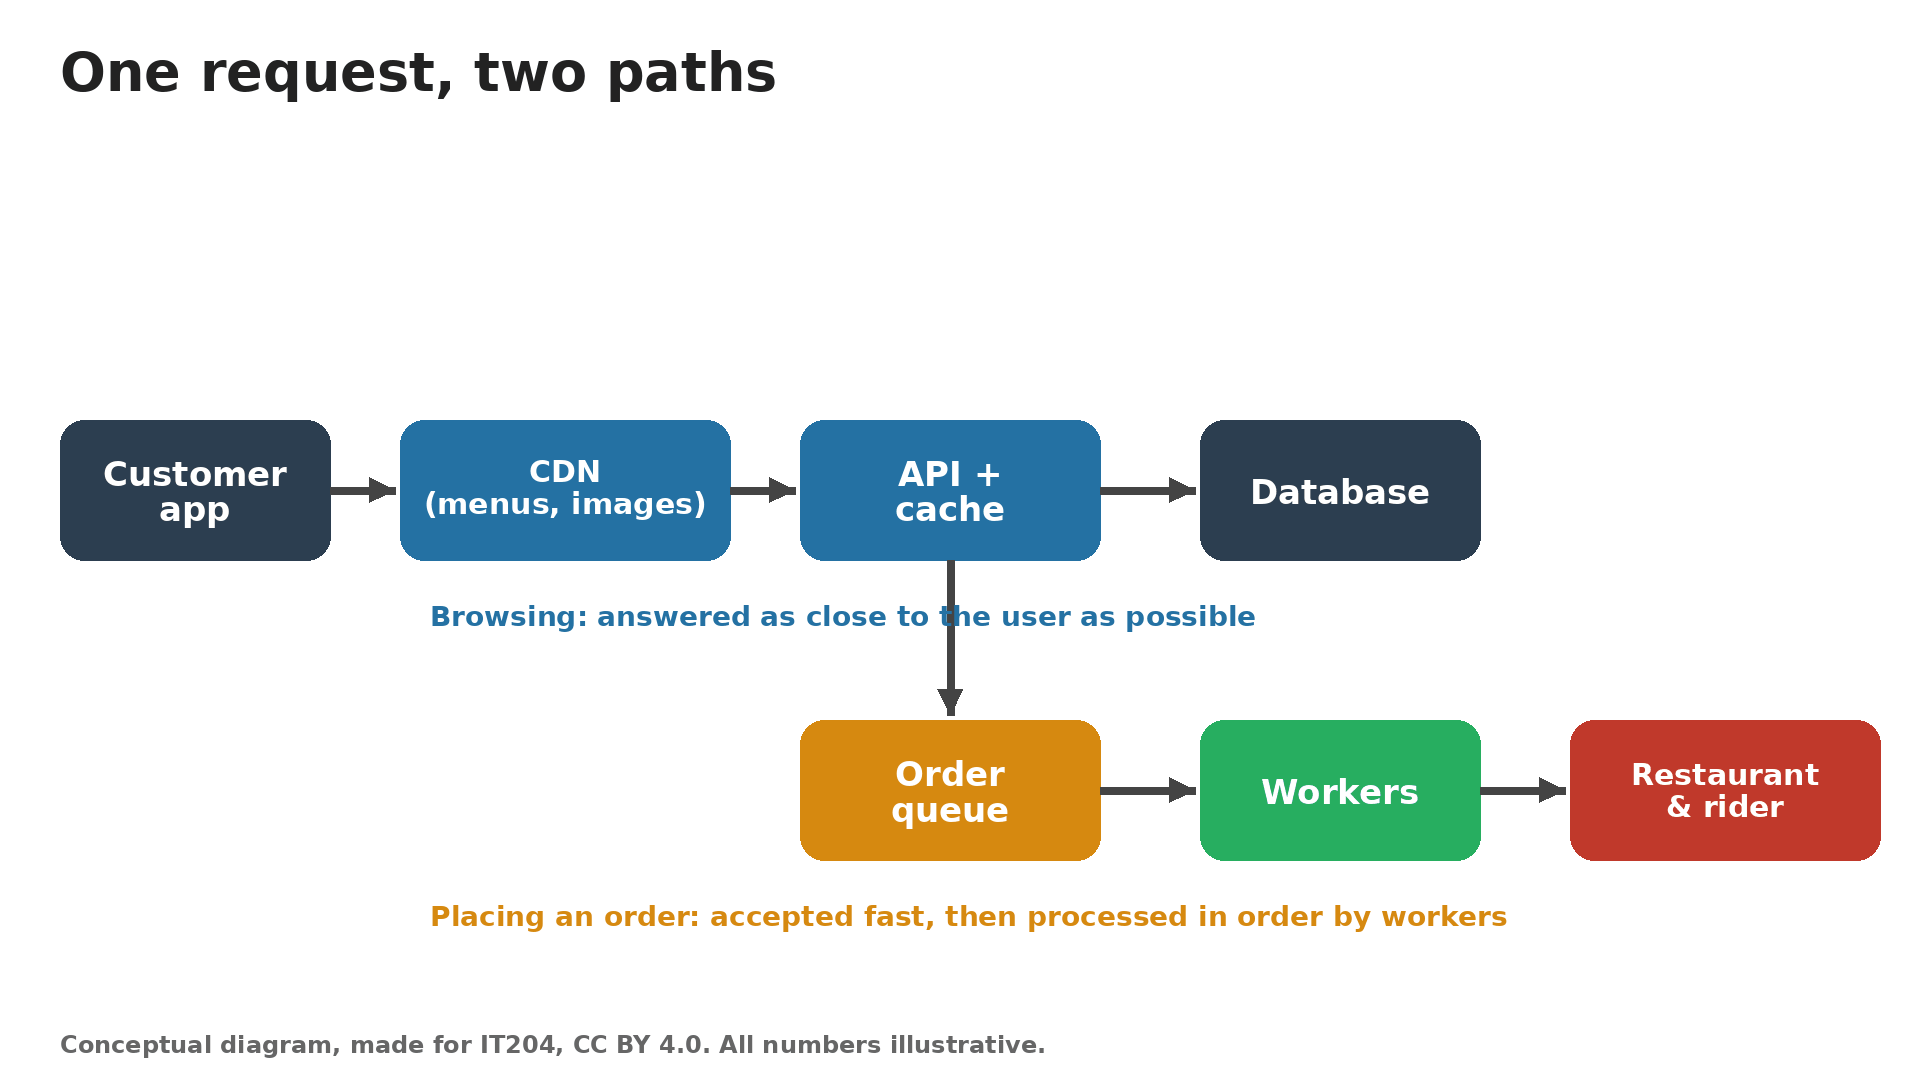
Request Path
📈 Worked Example: Scale Before the Queue Explodes
Illustrative load test: forecast 1,200 requests/second. One API instance safely handles 80 requests/second at its tested ceiling.
- Plan to use only 75% of that ceiling. How many ready instances are needed?
- Usable capacity per instance = 80 × 0.75 = 60 requests/second.
- Required instances = 1,200 ÷ 60 = 20 ready instances, assuming even traffic and the same workload.
- Pre-scale for a known event; test startup delays, service quotas, database connections and downstream capacity.
Twenty API instances cannot fix a database or kitchen that is already saturated. Scale the actual bottleneck and set a cost ceiling.
Layer 1: Caching Deep Dive ⚡
Where to Cache?
- CDN + Edge Caching: For static assets like images, logos, and restaurant menus that don't change often.
- Server-Side Caching: In-memory stores (like Redis) for "hot" data like popular categories or promotional items.
Why it Works
- Dramatically reduces database load.
- Makes browsing the app feel instant.
- Absorbs a huge percentage of user traffic before it hits the core infrastructure.
Interactive: Cache Hit Rate Calculator
Adjust CDN and server-side cache hit rates to see how much database load you can eliminate during a festival surge.
🧊 Cache the Menu, Not the Payment Decision
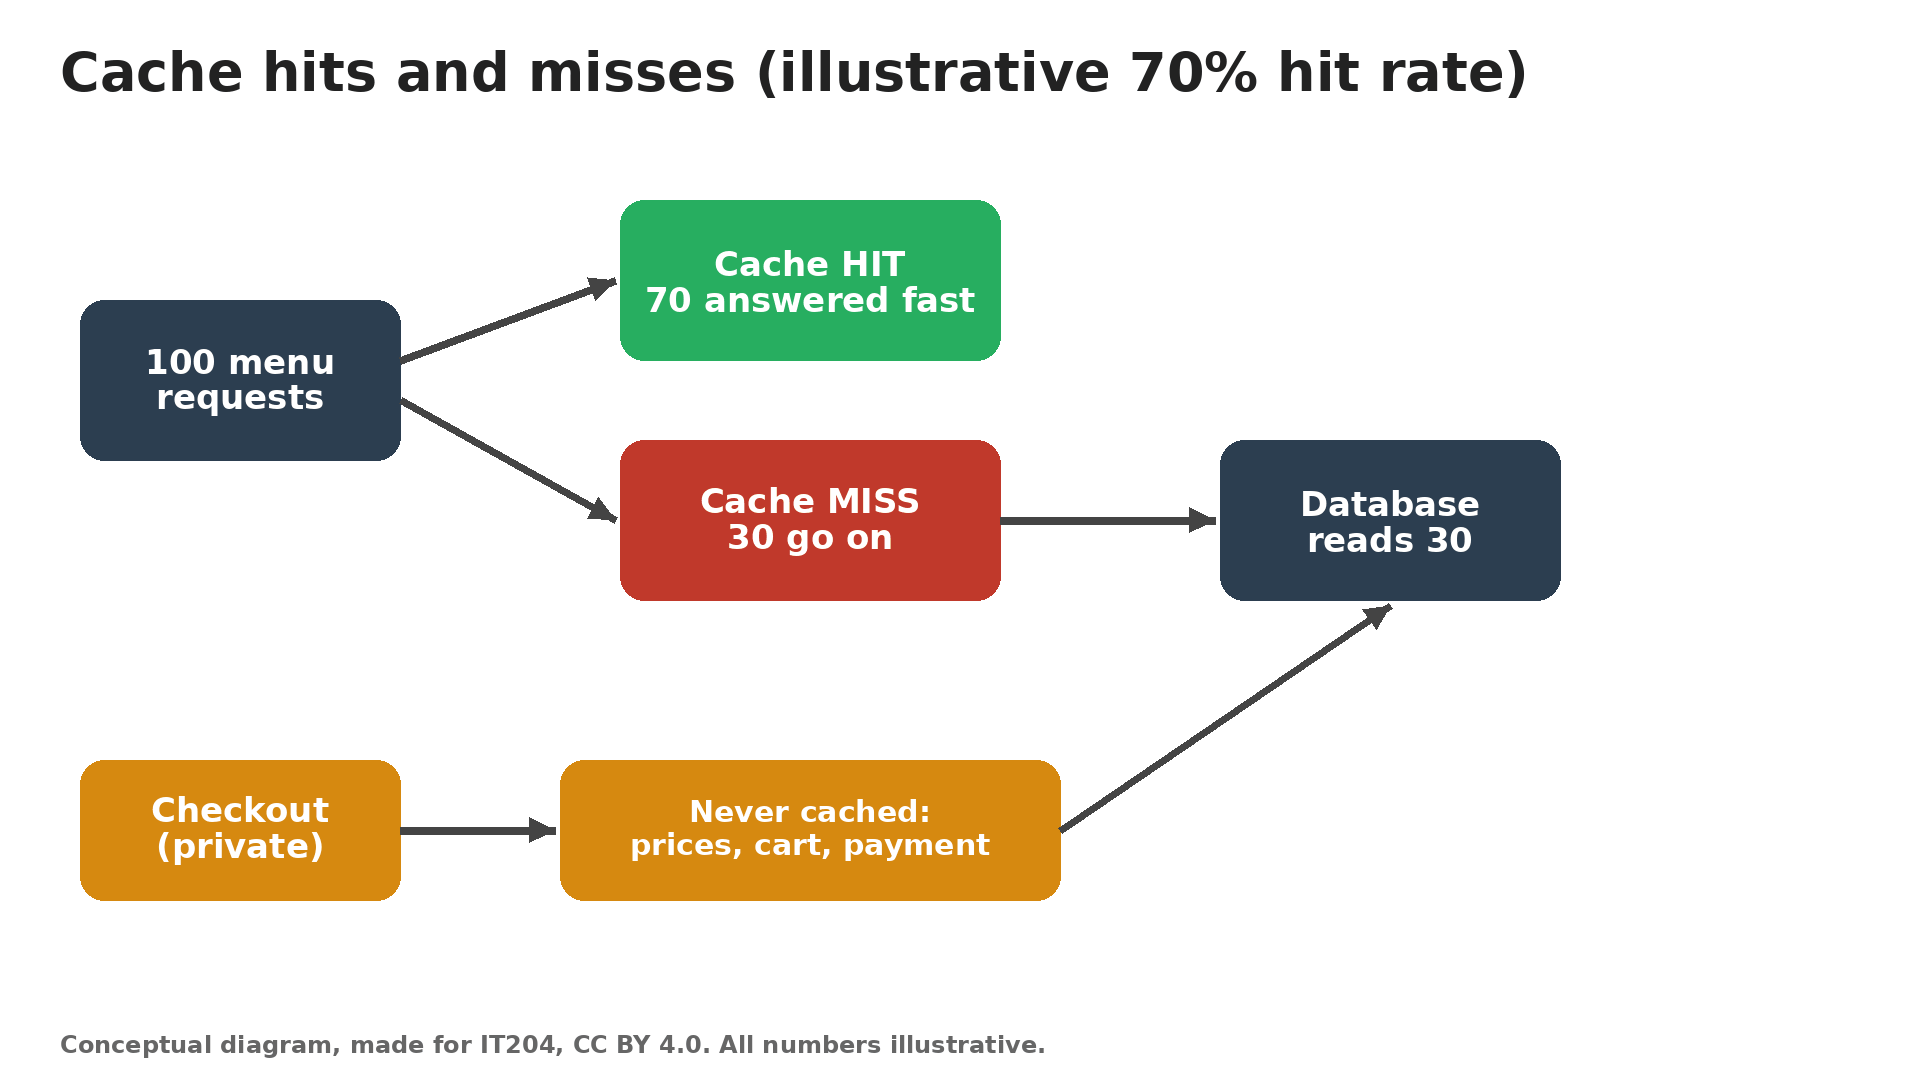
Illustrative model: 1,000 cache-eligible read requests; CDN hit rate 70%; server-cache hit rate 60% of CDN misses.
- After CDN: 1,000 × 0.30 = 300. After server cache: 300 × 0.40 = 120 database reads.
- Reduction = (1,000 − 120) ÷ 1,000 = 88%, not 70% + 60%.
- Public images and menu descriptions are good candidates. Price and availability need freshness checks; private balances and payment outcomes are not public cached pages.
- Pre-warm popular keys, expire or invalidate changed data, and avoid every cache entry refreshing simultaneously.
This model covers eligible reads only. It does not remove order writes or prove an end-to-end latency target.
Cache Hits and Misses
Layer 2: A Smarter Database 📊
Directly addressing the database bottleneck is critical for transactional stability.
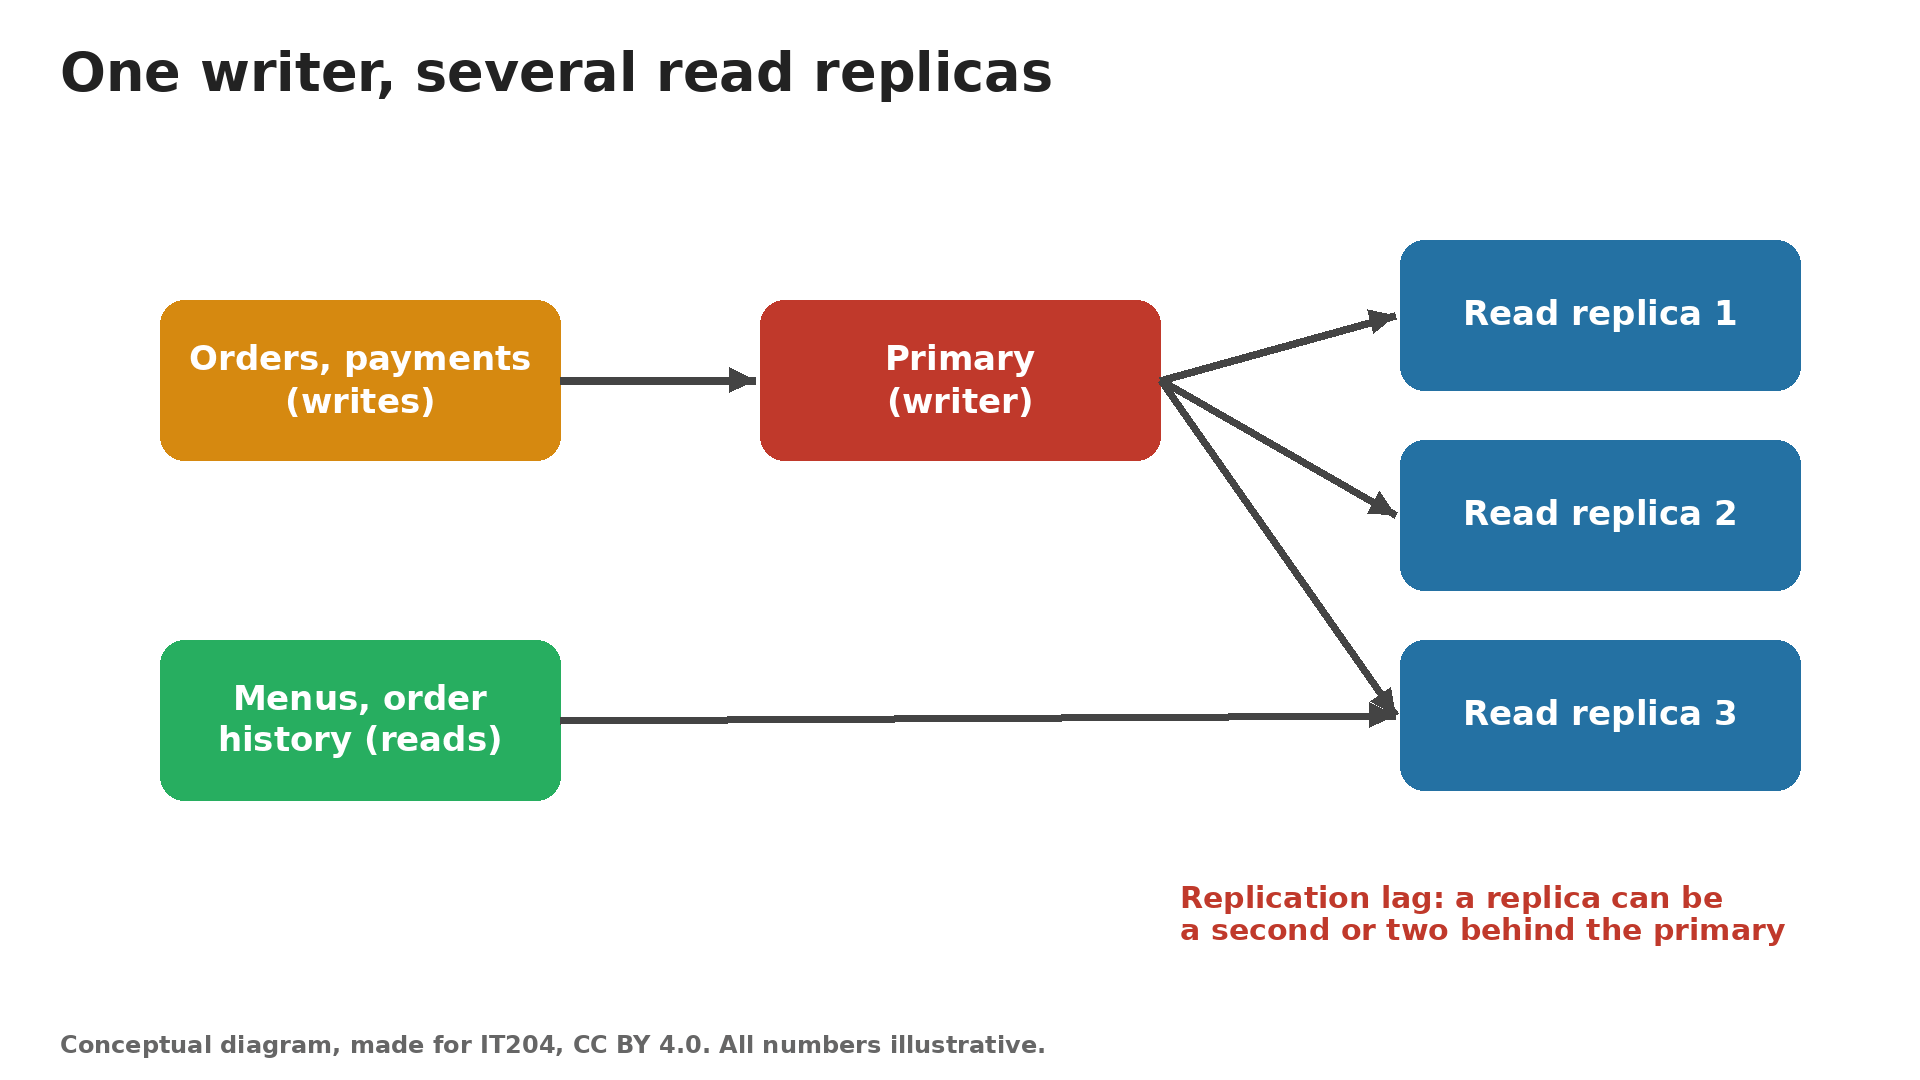
- Read Replicas: Created copies of the database dedicated to handling read-only requests (e.g., viewing menus, browsing restaurants). This isolates browsing traffic from order-placement traffic.
- Slow Query Optimization: Identified and fixed inefficient database queries that were consuming excessive resources, often by adding indexes.
- Connection Pooling: Reused a "pool" of active database connections instead of creating a new one for every request, reducing overhead.
Key Principle (Unit 3.3): Separate read vs. write paths to prevent contention and scale them independently.
Read Replicas
Layer 3: Resilient Order Processing
Key Concept: Message Queues. An intermediary service that holds "messages" (like a new order) in a queue. Services can pull messages to process them at their own pace, preventing the system from being overwhelmed.
The order lifecycle was decoupled:
Order Placed ➜ [Queue]
➜ Order Accepted ➜ [Queue]
➜ Rider Assigned ➜ [Queue]
➜ Delivered
This ensures that even if the "Rider Assignment" service is slow, it doesn't stop new orders from being placed.
Interactive: Queue vs. Direct Processing
Simulate 50 festival orders arriving simultaneously. Compare what happens with and without a message queue.
🎬 Watch: Queue Now, Process Next
⏳ Worked Example: A Queue Buys Time, Not Capacity
Illustrative burst: 800 orders/second arrive; workers process 600/second for 30 seconds. Start with an empty queue.
- How large is the backlog after the burst?
- Net growth = 800 − 600 = 200/second. Backlog = 200 × 30 = 6,000 orders.
- Then arrivals fall to 400/second. Spare processing capacity = 600 − 400 = 200/second: drain time = 6,000 ÷ 200 = 30 seconds.
- Monitor the oldest message, retry safely and deduplicate. If demand never falls below capacity, the queue keeps growing.
For food, an accepted order with an impossible wait is still a bad outcome. Bound waiting time and communicate delays.
Optimizing the 'Last Mile': Smart Dispatch
Improving operational efficiency for riders is just as important as server performance.
Geofencing
Virtual geographic boundaries were used to group riders into specific zones. This ensures riders are only offered deliveries within an efficient travel radius, reducing pickup times.
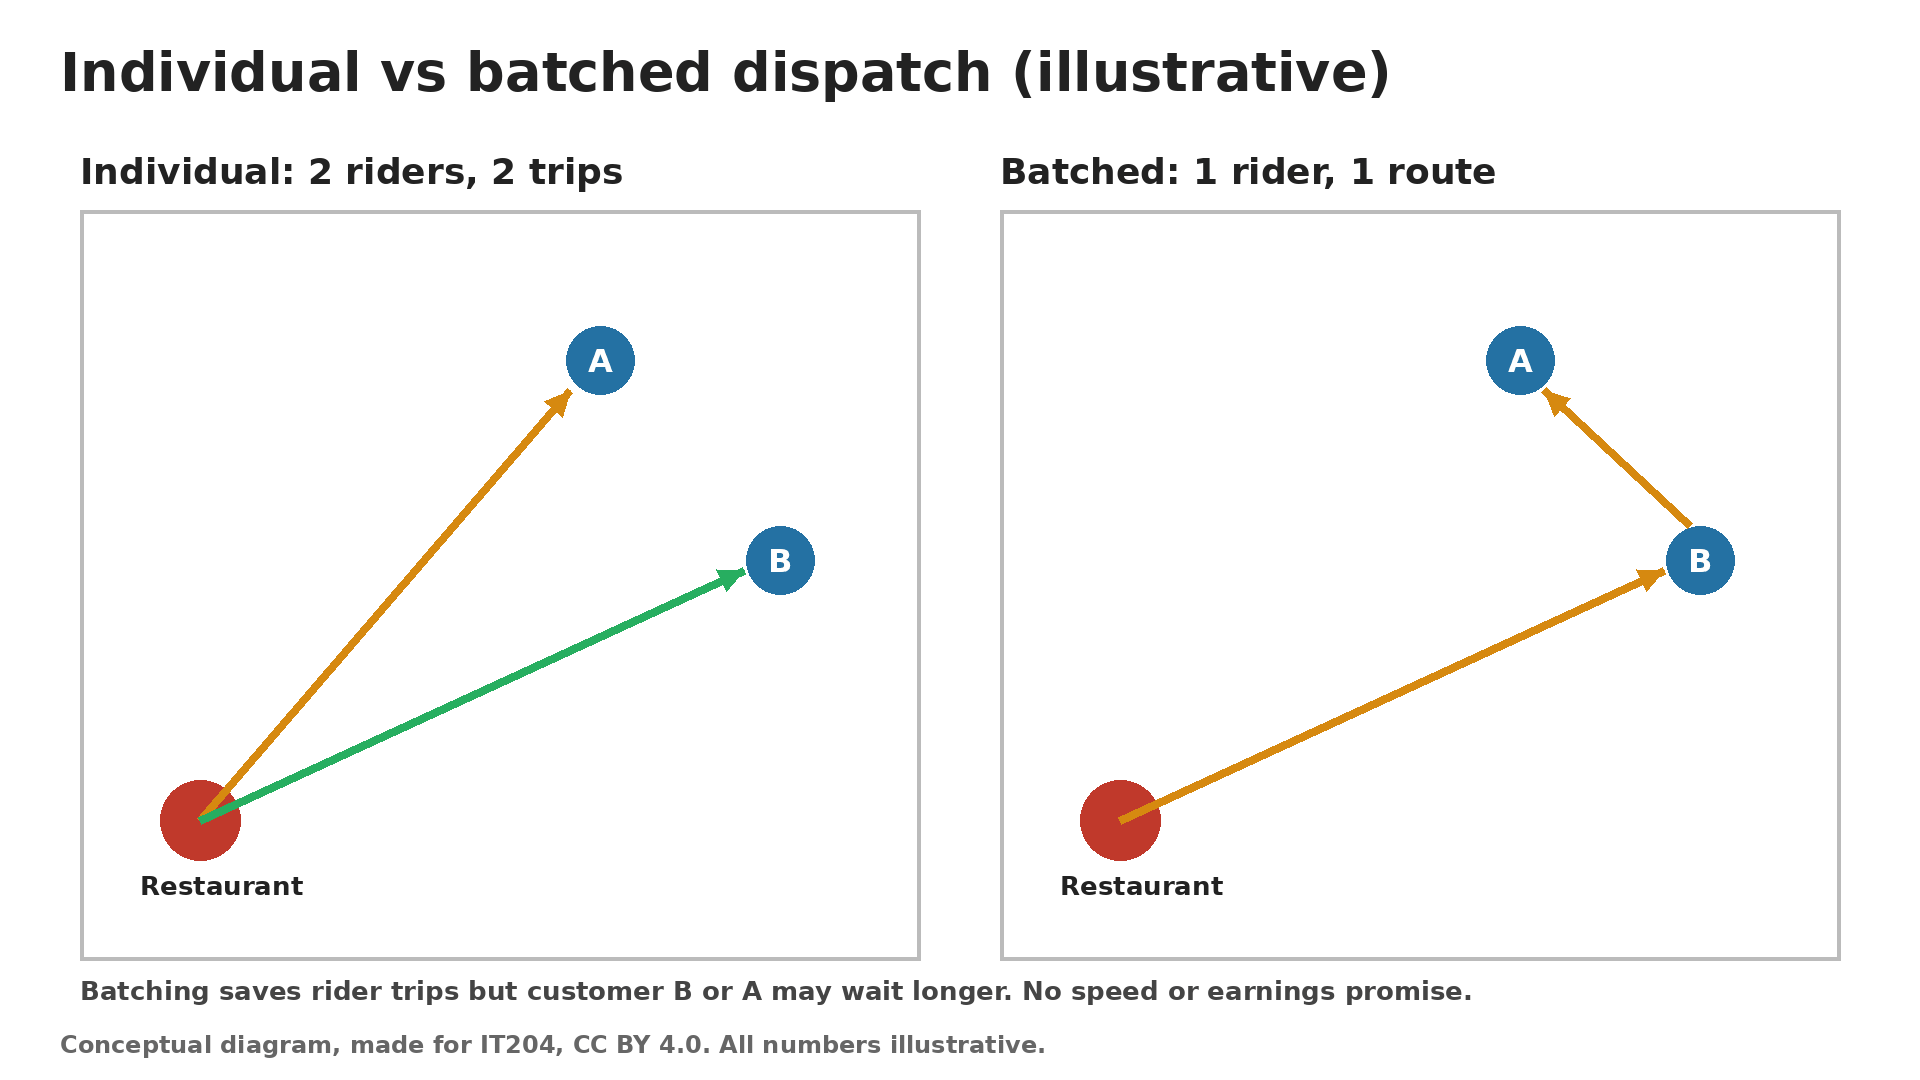
Batched Assignments
The system intelligently grouped multiple orders from the same area for a single rider. This increases rider earnings and delivery speed during peak hours.
Interactive: Individual vs. Batched Dispatch
4 orders arrive in the same zone. Choose a dispatch strategy and see the impact on riders, time, and cost.
Batched Dispatch
The Impact: Measurable Outcomes 🎯
BEFORE
- High P95 Latency
- High Order Failure Rate
- Erratic Rider Utilization
- Spike in Support Tickets
AFTER
- P95 Latency down 45%
- Failed Orders reduced by 70%
- More Stable Rider Utilization
- Fewer Customer Support Tickets
🚦 Festival Control Room: What Would You Do?
Illustrative results, not a company's measured performance: p95 API latency falls from 1,000 ms to 550 ms; failed-order rate falls from 10% to 3%.
- Latency reduction = (1,000 − 550) ÷ 1,000 = 45%. p95 describes the slow end, not the average.
- Failure reduction = (10 − 3) ÷ 10 = 70% relative, or 7 percentage points.
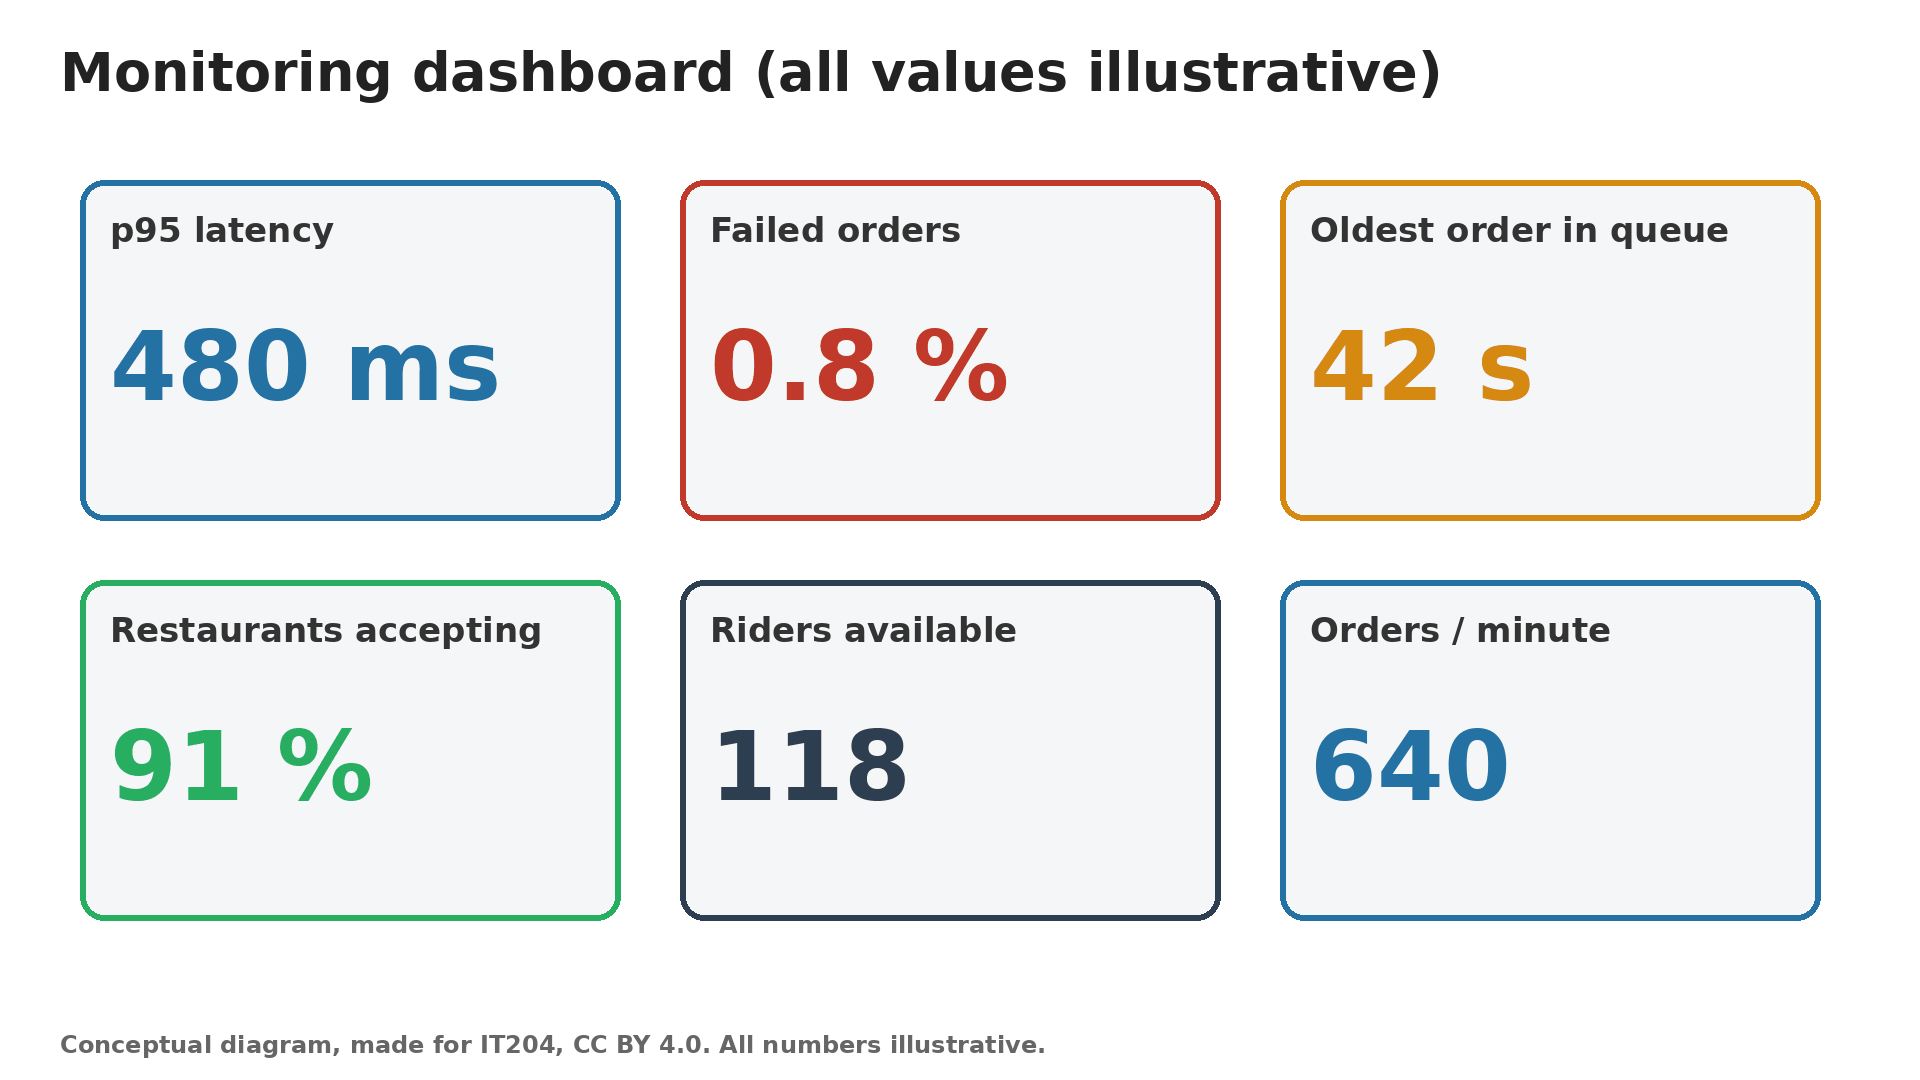
The API is now fast, but kitchen waits and oldest queue age keep rising. In pairs, choose: add API servers, extend honest delivery estimates, limit a delivery zone, or temporarily pause new orders.
Protect confirmed orders and rider safety. Transparent limits may be better than accepting orders the whole service cannot fulfil.
Ops Dashboard
Practical Application: The Nepali Context
Scenario: You are the CTO of a local e-commerce platform (e.g., Daraz, HamroBazar) preparing for the Dashain shopping festival.
Question: Based on this case study, what are your top 3 priorities?
- 🔍 Pre-warm Caches: Proactively load caches with "Dashain Deals" and top-selling product data before the sale begins.
- 📈 Pre-scale Infrastructure: Schedule autoscaling of read replicas and message queue workers to activate just before peak shopping hours (e.g., evening times).
- 📍 Logistics Planning: Use historical data to predict high-volume delivery zones in Kathmandu, Pokhara, etc., and pre-position delivery staff accordingly.
Interactive: Dashain Festival Readiness Score
You are the CTO preparing for Dashain. Check each action you have completed. Score your platform's readiness.
Summary: Key Takeaways
- Decouple with Queues: For any bursty, location-dependent workload, message queues are fundamental for building a resilient and scalable system.
- Cache Intelligently: A multi-layered caching strategy (CDN for static, Server-side for dynamic) is crucial to absorb read-heavy traffic.
- Isolate Read/Write Paths: Separating database read and write operations is one of the most effective ways to prevent system-wide slowdowns during peak traffic.
- Monitor and Prepare: Scalability isn't just about technology; it's about proactively monitoring capacity and planning for seasonal peaks.
Case Practice 📝
- Explain how caching and a content delivery network reduce the load on the platform's servers.
- Why does a message queue protect the system when orders arrive faster than they can be processed?
- The case says logistics is the final bottleneck. Explain this with reference to riders and restaurants.
- Is it fair to raise delivery fees or pause orders during peaks (traffic shaping)? Discuss from the customer's and the business's viewpoint.
- What should the platform monitor before the next festival to know whether it is ready?
Revise the answers in the full note.
Image & Video Credits
Images
- Delivery riders waiting: PattayaPatrol, CC BY-SA 4.0 (Wikimedia Commons)
- Request-path, cache, replica, dispatch and dashboard diagrams: made for IT204, CC BY 4.0
Videos (YouTube)
- Orders as Events (85–148 s)
- Queue Now, Process Next (11–94 s)
Thank You!
This case study covers concepts from Chapters 3.2-3.5.
Next Topic: Unit 4.1: E-commerce Security and Payment Systems